
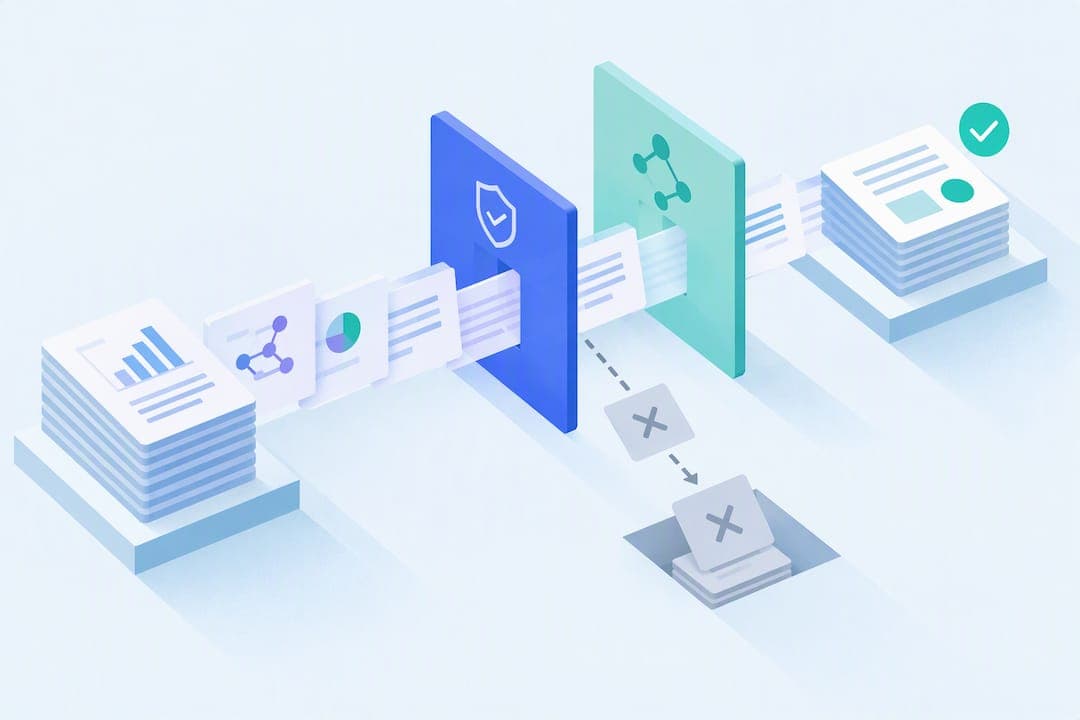
The fastest reliable way to summarize a research paper combines three moves: triage the paper to pick the right summary type, generate a draft with AI, then verify every claim against the source text before you edit it into final form. The one step you cannot skip is verification: an unchecked AI draft risks confabulation, confident but incorrect claims. Tools like AtListen can help structure that verified draft into a usable study package.
TL;DR:
- Summaries should be tailored to the specific purpose, whether abstract, structured note, or quick bullets, with length scaled to the paper's size.
- Breaking the paper into sections and extracting exact quotes for research question, methods, results, and limitations reduces errors and enhances accuracy.
- Factual verification involves generating questions from the draft and checking all responses against the source to prevent confabulation and incorrect claims.
- Grounding the AI in source text and using iterative QA verification significantly improves factual accuracy over single-pass summarization.
- Manual rewriting following a disciplined approach from writing centers remains essential to confirm clarity, objectivity, and traceability of all claims.
Table of Contents
- Quick triage: pick the right summary type and length for your goal
- AI-first generation: chunking, prompt templates, and model settings that improve grounding
- Verify and correct: a repeatable QA-based workflow to detect and fix confabulation
- Edit, condense, and format: templates and finishing moves for publishable summaries
- What research says about hallucination, trade-offs, and best practices
- A note on trusting AI with your reading
- A faster way to turn a verified summary into study material
- Sources
- FAQ
Quick triage: pick the right summary type and length for your goal
Before you write a single sentence, decide what kind of summary you actually need. A literature review needs something different from a study note you'll reread before an exam, and picking the wrong format wastes the time you're trying to save.
Three formats cover most academic use cases:
- Abstract-style summary: one paragraph, 150 to 250 words, mirrors the structure of a published abstract (background, methods, results, conclusion).
- Annotated note: a longer, structured summary of 400 to 600 words with subheadings for question, methods, findings, and limitations, useful when you'll cite the paper later.
- TL;DR bullets: 5 to 8 short bullets capturing only the finding and its significance, best for quickly scanning a stack of papers before deciding which ones deserve full attention.
Length should scale with the source, not with a fixed word count alone. A practical rule from university writing-center guidance is to aim for roughly 10 to 15% of the original paper's length for an annotated note, and far less, often under 5%, for a TL;DR pass. A 40-page dissertation chapter and a 6-page conference paper should not produce summaries of the same length.
Whichever format you choose, your summary needs to answer four questions clearly:
- What research question or hypothesis did the paper set out to test?
- What methods, sample, or data did the authors use to test it?
- What were the main results, stated without embellishment?
- What is the primary implication or the biggest limitation the authors themselves acknowledge?
Run this checklist before you generate anything. If you can't find the answer to one of these four questions on a first skim, that's the section to reread manually rather than delegate to a chunked AI prompt. Papers with unusual structures, mixed-methods studies, meta-analyses, or theoretical papers with no discrete "results" section, are also worth a manual first pass so you know where the load-bearing claims actually live before you start prompting a model.
The UConn Writing Center's guidance also recommends writing one sentence per section (introduction, methods, results, discussion) before condensing further. That habit, done manually or as an AI prompt instruction, forces you to engage with the paper's actual structure instead of skimming for keywords. It also gives you a natural checkpoint: if your one-sentence-per-section notes don't match what the AI draft claims later, you've caught a problem early.
AI-first generation: chunking, prompt templates, and model settings that improve grounding
Long papers overwhelm a single prompt. Splitting the paper into sections of roughly 400 to 900 words each, matching natural boundaries like abstract, methods, results, and discussion, keeps each chunk coherent and lets the model stay anchored to the text in front of it rather than guessing at the whole document's shape.
A workable generation sequence looks like this:
- Paste the abstract and ask for a one-sentence restatement of the research question, nothing else.
- Feed the methods section and ask the model to list the study design, sample, and key variables as plain bullets, extractive rather than interpretive.
- Feed the results section and ask for the main findings only, instructing the model to quote the exact number or direction of effect from the text rather than paraphrase it.
- Feed the discussion or conclusion and ask for the authors' own stated limitation and implication, distinguishing that from the model's own commentary.
- Combine the four outputs into a single draft and ask the model to tighten transitions without adding new claims.
Extractive prompts ("quote the exact sentence that states the sample size") produce fewer errors than abstractive ones ("explain what this study found") because they anchor the model to specific text rather than inviting it to synthesize. Use abstractive prompts only after you've extracted the load-bearing facts.
On model settings, lower temperature settings (closer to 0) reduce creative drift and are worth using for factual extraction steps, saving higher temperature for the final language-smoothing pass. Cap output length explicitly rather than letting the model run long, since longer generations give more room for invented detail to creep in. When a paper includes tables or figures with numeric claims, paste the table's exact text or caption into the prompt rather than describing it, so the model is grounded in the actual numbers rather than inferring them.
Pro Tip: Ask the model to mark any claim it could not find explicit textual support for with a bracketed note, then check those spots first during verification.
Verify and correct: a repeatable QA-based workflow to detect and fix confabulation
Once you have a draft, the verification pass is what separates a usable summary from a risky one. A QA-based hallucination detection framework generates factual questions from the draft, answers them from the source, and flags any mismatch, and this approach improved factual consistency on scientific summarization benchmarks tested on PubMed and ArXiv papers.
Apply the same logic manually or with a model's help:
- Generate 8 to 12 factual questions from your draft, prioritized by how central the claim is to the paper's argument.
- Answer each question strictly from the source text, not from memory or from the draft itself.
- Flag any answer that doesn't match, then correct all flagged items in one consolidated revision rather than piecemeal edits.
- Check every number, statistic, and citation in the draft against the exact sentence in the source that states it.
Studies on iterative correction methods show factuality gains through several rounds of QA-based verification, but diminishing and sometimes negative returns beyond that, since excessive rounds of correction can start stripping out useful detail along with errors. A practical target is several verification passes before you move to manual editing, avoiding an open-ended loop.
Numeric claims deserve the strictest scrutiny. If a paper reports a sample size, an effect size, or a p-value, the summary should reflect this data carefully, preferably matching the original source where possible. When a number doesn't materially change the summary's meaning, it's often safer to describe the direction of the effect qualitatively than to risk a model inventing a decimal point that was never in the paper.

Edit, condense, and format: templates and finishing moves for publishable summaries
The verified draft still needs a human edit pass before it's ready to use or share. Run through a short checklist: confirm the summary stays in third person and present tense for findings, confirm every sentence describes what the paper says rather than adding your own judgment, and confirm nothing in the final version lacks a traceable source sentence.
- Cut redundant qualifiers and any sentence that restates a point already made.
- Preserve the research question, method, primary result, and stated limitation even when cutting length aggressively.
- Note explicitly when AI assistance was used in drafting, consistent with the provenance and disclosure practices recommended in NIST's Generative AI risk guidance.
- Keep citations in the format your field expects, and never let the summary imply a claim the original paper doesn't make.
Two templates cover most needs: a one-paragraph abstract-style summary of 4 to 6 sentences (question, method, result, implication), and a structured summary of four short paragraphs, one each for background, methods, results, and discussion, running 2 to 4 sentences per paragraph.
| Element | Abstract-style summary | Structured summary |
|---|---|---|
| Length | 4 to 6 sentences | 4 paragraphs, 2 to 4 sentences each |
| Best use | Quick reference, citation lists | Notes for later writing or review |
| Includes limitation | Often one clause | Dedicated paragraph |
What research says about hallucination, trade-offs, and best practices
Generative models can produce fluent, confident text that is factually wrong, a failure mode NIST's AI Risk Management Framework identifies as confabulation and treats as a central risk of generative AI systems, recommending pre-deployment testing and post-output verification as primary mitigations.
The trade-off between polish and accuracy is not hypothetical. Comparative research on LLM reasoning for summarization found that more elaborate internal reasoning during generation often improves fluency scores without reliably improving factual faithfulness, while simpler grounding combined with iterative correction produced better factual accuracy on long scientific texts. A separate staged pipeline tested on medical summarization benchmarks found that removing confabulated content first, then adding back missing key information, improved both factuality and informativeness compared to single-pass generation.
- Confabulation is a named, documented risk in generative AI guidance, not an edge case.
- Grounding the model in exact source text beats asking it to reason more elaborately.
- Iterative QA-style correction consistently outperforms a single creative pass in published evaluations.
Grounding plus iterative correction improves factual accuracy for long-form summarization more reliably than complex reasoning alone.
University writing centers arrived at a compatible answer decades before generative AI existed: scan each section, write one sentence per part, then condense. That manual discipline, described in guidance from UConn's Writing Center, works as a verification anchor for an AI draft just as well as it works as a standalone method.
A note on trusting AI with your reading
I don't let an AI draft stand as the final word on what a paper claims. My habit is simple: generate the draft fast, then check every number and every causal claim against the actual sentence it came from before I trust any of it. Tools like AtListen fit into that habit well, since generating the structured draft quickly is only useful if the verification step still happens afterward.
— William
A faster way to turn a verified summary into study material
Once you've verified a summary, the harder problem is often what to do with it next: turning scattered notes into something you can actually study from. Some tools take a verified summary, or the raw paper itself, and structure it into key concepts with definitions, practice questions with explanations, and flashcards built for spaced repetition, with depth control so users can go lighter or deeper depending on how much time they have before an exam.
The Free plan lets you try the workflow on your own reading list, while Pro at $19.99 per month and Max at $39.99 per month unlock higher usage limits and deeper study packages for heavier course loads. If you're already summarizing papers by hand, see what a structured study package looks like on Atlisten.
Sources
- Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
- Hallucination detection and mitigation framework for summarization (PMC)
- How to summarize a research article (UConn Writing Center)
- uMedSum: A unified framework for advancing medical abstractive summarization (arXiv 2024)
FAQ
How do I summarize a research paper?
Triage the paper to pick a summary format, generate a first draft with AI using section-by-section prompts, then verify every claim against the source text before editing for clarity. This AI-first, verification-focused approach follows guidance from university writing centers and reduces the risk of confabulated claims.
Can AI summarize a research paper?
Yes, AI can draft a research paper summary quickly, but generative models are prone to confabulation, producing fluent but factually wrong statements, according to NIST's Generative AI risk guidance. Every AI-generated draft needs a verification pass against the source before you treat it as final.
What are the 5 techniques in summarizing?
Definitions of summarizing techniques vary across writing guides, but a common set includes: identifying the main idea, distinguishing key points from supporting detail, paraphrasing rather than quoting, condensing repeated or redundant information, and reviewing for objectivity and accuracy. University writing-center guidance frames these as scanning for research question, methods, results, and discussion before condensing.
What is a research summary example?
A research summary typically states the research question, the method used to test it, the main result, and the paper's own stated limitation or implication, usually in one paragraph of 4 to 6 sentences for an abstract-style version. A structured version splits those same elements into short paragraphs, one each for background, methods, results, and discussion.
How do I verify an AI-generated summary is accurate?
Generate factual questions from the AI draft, answer each one strictly from the source paper, and flag any mismatch for correction. This QA-based approach, described in research on hallucination detection in scientific summarization, improved factual consistency in published evaluations and works well within four to six verification passes.